

An Interactive 5-Day Training Course
Subsurface Uncertainty Quantification using Machine Learning
Machine Learning for Subsurface Uncertainty Quantification
Secure your spot now!
Duration
5 Days
Price
$ 3,500
Starting From
12 Jul 2027



Home Geology and Geoscience Subsurface Uncertainty Quantification using Machine Learning
Subsurface Uncertainty Quantification using Machine Learning
Have Questions ?
Subsurface Uncertainty Quantification using Machine Learning - GG-UQML-PEA27
| Code | Date | Time | Duration | Location | Currency | Early Bird Fee Per Person |
|---|---|---|---|---|---|---|
| GG-UQML-PEA27 | 12 - 16 Jul 2027 | 10 AM CST | 4 Hours Per Day |
Online |
USD |
3500 |
Need this for a group? We deliver the same course in-house — face-to-face at your location or online — tailored to your assets and team level. Contact info@peassociations.com
Boost your team's skills and your budget! Enjoy group discounts for collaborative learning. Send an inquiry to info@peassociations.com.
Subsurface Uncertainty Quantification using Machine Learning
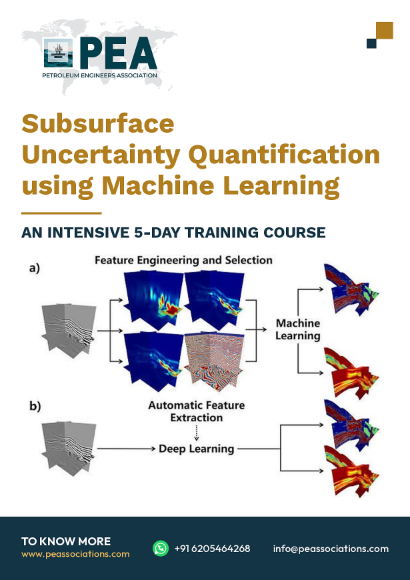
This training covers machine learning applied to subsurface uncertainty quantification. It works through the uncertainty problem and why it is computationally hard, supervised learning fundamentals, surrogate and proxy models, experimental design for training sets, uncertainty in the predictions themselves, Bayesian methods and inversion, ensemble and history matching applications, validation requirements and the recognition of models that have learned the wrong thing.
Description
Quantifying subsurface uncertainty properly requires running many models, and the models are expensive to run. A full field simulation may take hours, so exploring a hundred-dimensional uncertainty space by brute force is impossible. Machine learning offers a route: train a fast approximation on a limited number of expensive runs, then use the approximation to explore the space thoroughly. This works well when done carefully and produces confident nonsense when done carelessly, and the difference is in the validation.
This training covers the methods and their pitfalls. The uncertainty problem and why it is computationally hard are established first, framing what the machine learning is being asked to do. Supervised learning fundamentals follow, covering regression and classification, training and the bias-variance trade-off at the level needed. Surrogate and proxy models are then developed as the main application. Experimental design for training sets follows, since the quality of a surrogate depends mostly on how the training runs were chosen. Uncertainty in the predictions themselves is then addressed, covering methods that report their own confidence. Bayesian methods and inversion follow. Ensemble and history matching applications are then developed. Validation requirements follow. The training closes with the recognition of models that have learned the wrong thing.
A surrogate model is only valid where it was trained. A proxy trained on a hundred simulation runs covering a particular range of permeability, contact depth and fault transmissibility will reproduce the simulator accurately within that range and can be badly wrong outside it, with no indication that anything is amiss. Because the purpose of the surrogate is usually to explore the space quickly, the temptation to evaluate it at the edges and beyond is strong. Recording the training domain and refusing to predict outside it is a necessary discipline.
The experimental design matters more than the algorithm. Given a fixed budget of expensive simulation runs, the choice of which parameter combinations to run determines how much the surrogate can learn. A space-filling design such as Latin hypercube covers the space efficiently; a design that varies one parameter at a time learns nothing about interactions; and a design concentrated in one region produces a surrogate that is accurate there and useless elsewhere. Effort spent on the design pays more than effort spent selecting between regression methods.
A model that reports its own uncertainty is worth more than a more accurate one that does not. Gaussian process regression, Bayesian neural networks and ensemble methods all give a prediction with a confidence interval, which widens in regions where the training data was sparse. For uncertainty quantification that is exactly what is needed: it tells you where the surrogate can be trusted and where more expensive runs are required. A point prediction from a method with no uncertainty estimate cannot be used for this purpose safely.
Finally, validation must be out of sample and preferably out of region. Testing a surrogate on data randomly held out from the training set measures how well it interpolates between training points, which is the easy case and usually looks excellent. Testing it on runs from a region of the parameter space not represented in training measures whether it extrapolates, which is the case that matters. For spatial problems, holding out whole wells or whole areas rather than random points is the equivalent requirement, and models that pass random validation frequently fail this one.
By the end of this training, participants will be able to:
- Frame subsurface uncertainty problems for machine learning approaches
- Apply supervised learning fundamentals including the bias-variance trade-off
- Build surrogate and proxy models of expensive simulations
- Design experimental training sets using space-filling methods
- Select methods that report prediction uncertainty
- Apply Bayesian methods to subsurface inversion problems
- Apply ensemble methods to history matching and forecasting
- Validate models out of sample and out of region
- Define and respect the domain of validity of a trained model
- Recognise models that have learned a spurious relationship
The training works on simulation and field data sets. Participants build surrogate models from simulation ensembles, compare the effect of different experimental designs on surrogate quality, and test surrogates inside and outside their training domain to see the failure. Models are deliberately trained on confounded data to demonstrate how plausible and wrong results arise.
Organisations sending participants to this training will:
- Explore uncertainty spaces that brute force cannot reach
- Design simulation ensembles that support surrogate building
- Use methods that report their own confidence
- Validate models properly before relying on them
- Respect the domain of validity of trained models
- Avoid confident conclusions from spurious relationships
Participants will:
- Build surrogate models of expensive simulations
- Design training experiments effectively
- Quantify prediction uncertainty
- Apply Bayesian inversion methods
- Validate models rigorously
- Recognise and reject unreliable models
- Reservoir engineers working on uncertainty and forecasting
- Geoscientists applying machine learning to subsurface problems
- Data scientists working with subsurface data
- Reservoir modellers building ensembles
- Technical staff performing uncertainty quantification
- Simulation engineers using proxy models
- Technical staff reviewing machine learning studies
Module 1 - The Uncertainty Problem
- Uncertainty quantification objectives
- Parameter and scenario uncertainty
- Dimensionality of subsurface uncertainty
- Computational cost of full physics models
- Sampling requirements for high dimensions
- Curse of dimensionality
- Why brute force fails
- Role of approximation
- Dimension reduction approaches
- Identifying the influential parameters first
- Framing the problem for machine learning
- What machine learning can and cannot add
Module 2 - Supervised Learning Fundamentals
- Regression and classification
- Features, targets and training data
- Linear and polynomial regression
- Regularisation and its purpose
- Decision trees and ensembles
- Random forests and gradient boosting
- Support vector methods
- Neural networks in outline
- Bias and variance trade-off
- Overfitting and its symptoms
- Cross validation
- Method selection considerations
Module 3 - Surrogate and Proxy Models
- Surrogate model concept
- Response surface methods
- Polynomial proxies
- Kriging and Gaussian process surrogates
- Neural network surrogates
- Reduced physics proxies
- Streamline based proxies
- Surrogate accuracy requirements
- Speed gain from surrogates
- Domain of validity definition
- Extrapolation failure modes
- Updating surrogates with new runs
Module 4 - Experimental Design
- Design of experiments for training sets
- Full and fractional factorial designs
- Latin hypercube sampling
- Space-filling design properties
- Sobol and quasi-random sequences
- Design size and dimension relationship
- Sequential and adaptive designs
- Active learning for run selection
- One at a time designs and their failure
- Design for interaction detection
- Budget allocation between design and validation
- Designs for categorical scenarios
Module 5 - Prediction Uncertainty
- Why prediction uncertainty matters
- Gaussian process regression
- Kernel selection and hyperparameters
- Predictive variance interpretation
- Bayesian neural networks
- Ensemble based uncertainty estimates
- Bootstrap and bagging approaches
- Quantile regression
- Distinguishing model from data uncertainty
- Using uncertainty to select further runs
- Reporting predictions with intervals
- Methods without uncertainty estimates
Module 6 - Bayesian Methods and Inversion
- Bayesian framework and notation
- Prior, likelihood and posterior
- Prior specification for subsurface parameters
- Likelihood from data mismatch
- Markov chain Monte Carlo methods
- Convergence assessment
- Computational cost and surrogate use
- Approximate Bayesian computation
- Variational methods
- Inversion of production data
- Inversion of seismic data
- Interpreting posterior distributions
Module 7 - Ensemble Methods and History Matching
- Ensemble based uncertainty workflows
- Ensemble Kalman filter
- Ensemble smoother methods
- Assisted history matching
- Parameterisation for ensemble methods
- Ensemble collapse and its avoidance
- Localisation techniques
- Forecast uncertainty from matched ensembles
- Honouring geological plausibility
- Preserving scenario diversity
- Comparing against manual matching
- Interpreting ensemble results
Module 8 - Validation and Failure Recognition
- Out of sample validation
- Random holdout and its limitations
- Out of region validation
- Spatial and blind well validation
- Blind scenario validation
- Validation metrics selection
- Confounded variables in training data
- Spurious correlations
- Data leakage mechanisms
- Models that learn the wrong thing
- Interpretability and feature importance
- Deciding whether to trust a model
Upon successful completion of this training course, delegates will be awarded an official Certificate of Completion issued by the Petroleum Engineers Association (PEA), an ISO 9001:2015 certified training organization. The certificate carries 10 Credits and formally records the total learning hours completed.
Each certificate is signed by the Course Facilitator and the CEO of the Petroleum Engineers Association, and serves as verifiable proof of professional training that delegates can present to employers and professional bodies worldwide.
Frequently Asked Questions
All course bookings made through PEA are strictly non-refundable. By registering for a course, you acknowledge and accept that all fees are payable in full and are not subject to refund under any circumstances, including changes in personal or professional commitments or partial attendance.
PEA reserves the right to make reasonable adjustments to course content, trainers, or schedules where necessary, without entitling delegates to a refund. Comprehensive details of each course — including objectives, target audience, and content — are clearly outlined before enrolment, and it is the responsibility of the delegate to ensure the course's suitability prior to booking.
For any inquiries related to cancellations or bookings, please contact our support team, who will be happy to assist you.
